Classify, explain and rewrite Turkish hate-speech tweets.
Multilingual BERTLoRA / PEFTSHAPLLaMA 3Python
The problem
Moderating hate speech in a lower-resource language needs more than a label. Moderators need to know why a tweet was flagged, and authors benefit from a respectful alternative.
Approach
Fine-tuned bert-base-multilingual-cased with LoRA on a 4-bit quantised model, which keeps training cheap.
Trained on about 16k Turkish tweets labelled hateful (nefret) or not hateful (hiçbiri).
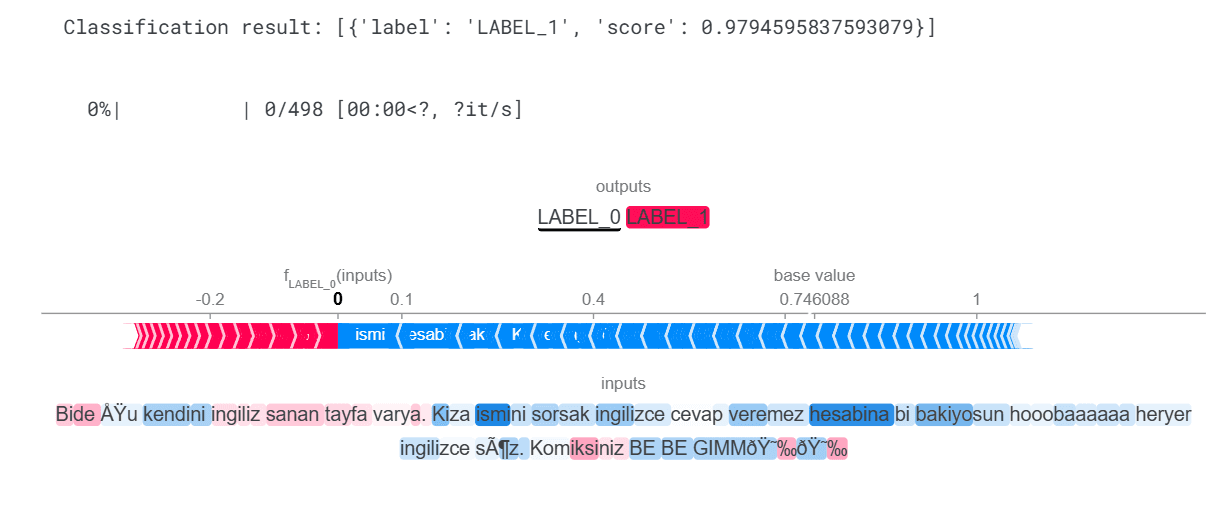
Used SHAP to show which tokens drove each prediction.
Used LLaMA-3 to paraphrase hateful tweets, keeping the tone but removing offensive phrases.
Results
End-to-end pipeline: classification, token-level explanation and rewriting.
Reports accuracy, macro F1, precision and recall. See the repo for the figures.
Dataset published on Kaggle with EDA and visualisations.
At a glance
Pipeline
Tweet
↓→
Classifier
mBERT + LoRA, 4-bit
↓→
Explanation
SHAP token scores
↓→
Rewrite if hateful
LLaMA-3
Trained on about 16k Turkish tweets labelled nefret (hateful) or hiçbiri (not hateful).